Claude Code “Safeguards Flagged This Message”: What It Means and How to Fix It
“API Error: Fable 5.2’s safeguards flagged this message” in Claude Code means a safety check on that model stopped your request. It is not a network fault or a bug in your install. The Details line at the end, such as [reasoning_extraction] or [cyber], tells you which check fired and which fix applies.
API Error: Fable 5.2's safeguards flagged this message (https://www.anthropic.com/legal/aup). This sometimes happens with safe, normal conversations. Claude Code can't respond to this message with Fable 5.2.

Double press esc to edit your last message, or try a different model with /model.

Send feedback with /feedback or learn more: https://support.claude.com/en/articles/15363606

Details: `[reasoning_extraction]`

Request ID: req_...
Message ID: msg_...
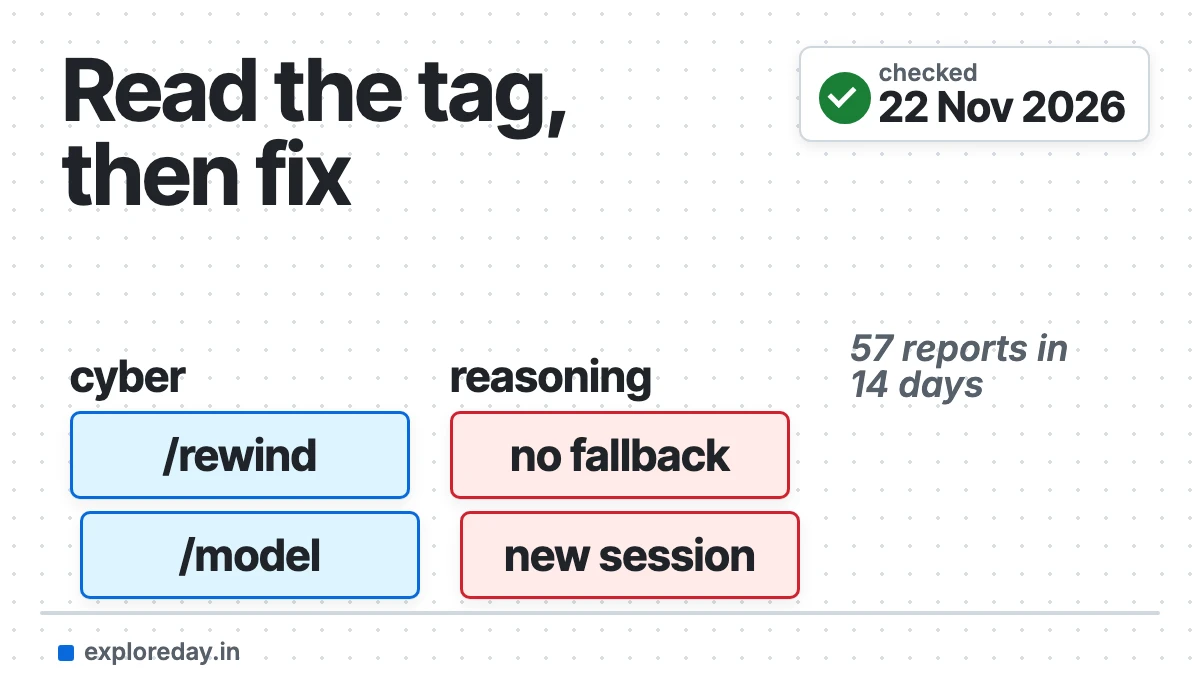
Quick answer: Read the Details tag. For [reasoning_extraction], remove any instruction that asks Claude to write out its thinking, then start a new session. For [cyber], step back with Esc Esc or switch model with /model. Report false alarms with /feedback.
Checked, not tested: Claude Code 2.1.330, macOS 26.7.1 (Apple Silicon), 22 November 2026. I did not trigger this error and did not try to. Every error text is copied from public GitHub issues and Anthropic’s docs, linked below. I ran only the commands shown with output. Drafted with AI assistance (Claude) and checked against the official docs.
Fix it in order
- Read the tag on the
Detailsline:[reasoning_extraction],[cyber],[bio],[frontier_llm]or[general_harms]. - Edit the message: press Esc twice, or run
/rewind, and reword the turn that was stopped. - For
[reasoning_extraction]: delete any “show your thinking” wording from your prompt, CLAUDE.md, skills and subagent prompts. - Test without your setup: quit, run
claude --safe-mode, and send the same prompt. - Start clean: run
/clear, or open a new session. Don’t use--resumeor--continue. - Still blocked: try
/model, then send/feedbackand keep the Request ID.
Steps 2 to 5 come from Anthropic’s docs. Step 6 is printed in the error itself. The sections below give the source for each one.
What does “safeguards flagged this message” mean in Claude Code?
It means a safety classifier (an automatic filter on the model) declined your request. Anthropic’s API docs say these models “include safety classifiers that can decline a request”. The API returns a refusal, and Claude Code prints it as this error.
The check reads more than your last line. Anthropic’s help article says:
The checks also review everything the model reads, not just your latest message—including memory, content from connectors, web search results, and files, so a block can be triggered by content you didn’t type.
That is why a plain “hi” can be stopped. The cause may sit in your CLAUDE.md, a skill, a file Claude read, or an older turn.
What the Details tag means: reasoning_extraction, cyber and the rest
The Details tag is the API’s refusal category. The wording below is quoted from Anthropic’s refusal category table, read on 22 November 2026.
| Tag | Anthropic’s wording | Billed if blocked before any output |
|---|---|---|
[reasoning_extraction] |
“The request asks the model to reproduce its internal reasoning in the response text.” | Yes |
[cyber] |
“The request could enable cyber harm, such as malware or exploit development. Benign cybersecurity work can also trigger this category.” | No |
[bio] |
“The request could enable biological harm, such as dangerous lab methods. Beneficial life sciences work can also trigger this category.” | Yes |
[frontier_llm] |
“The request could help with the development of competing AI models”. “Benign machine learning work can also trigger this category.” | Yes |
[general_harms] |
“The request falls under a usage-policy area outside the four named categories. Benign work can also trigger this category.” | No |
Two facts matter most. A reasoning_extraction block has no fallback model, so Claude Code can’t switch models for you. And it is billed even when no answer comes back.
Claude Code only prints this tag from v2.1.234, per its errors reference. On older versions the Details line is missing.
The other versions of the error text
The wording changes with the model and the category. These three are copied from GitHub reports. I added line breaks where a report pasted one long line.
The cyber form, from #110956 on v2.1.327. It matches the official example word for word:
API Error: Opus 4.8's safeguards flagged this message. Our intentionally broad safeguards allow us to deliver more capabilities faster, but can sometimes flag legitimate cybersecurity work. Send feedback with /feedback or learn more: https://support.claude.com/en/articles/14604842-real-time-cyber-safeguards-on-claude

Details: `[cyber]`
The “this session” form on Opus 5.5, from #108500 on v2.1.319:
API Error: Opus 5.5's safeguards flagged this session (https://www.anthropic.com/legal/aup). You may be seeing this for the first time: Opus 5.5 is more capable and has stronger safeguards as a result, which can sometimes flag non-cybersecurity work. We're improving these safeguards to reduce the amount of incorrectly flagged messages. Claude Code can't respond to your last message with Opus 5.5.

Double press esc to edit your last message, or try a different model with /model.

Send feedback with /feedback or learn more: https://support.claude.com/en/articles/8106465

Details: `[cyber]`
The model-switch notice, from #110781 on v2.1.325. Here Claude Code carried on with another model:
⏺ Fable 5.1's safeguards stopped the response above · continuing once with that noted

⏺ Fable 5.1's safeguards flagged this message. Our intentionally broad safeguards allow us to deliver more capabilities faster, but can sometimes flag legitimate coding and cybersecurity tasks. Switched to Opus 4.8. Send feedback with /feedback or learn more

  Details: `[cyber]`
The top-of-page text is from #109211 on v2.1.322. I cut the request and message IDs from all four.
How to fix a reasoning_extraction block
Remove any instruction that asks Claude to write its thinking into the answer. That is the official fix in the errors reference. It names a <thinking> section, a scratchpad section, and a reasoning field in JSON output.
The wording may not be in your prompt. The same page lists CLAUDE.md, a skill, a subagent prompt, an output style, and an MCP tool description. Here is a rough search of my own setup:
$ grep -c -i -E "<thinking>|<reasoning>|scratchpad|chain of thought|step by step reasoning" ~/.claude/CLAUDE.md
0
$ grep -rl -i -E "<thinking>|<reasoning>|scratchpad" ~/.claude/skills ~/.claude/agents ~/.claude/output-styles 2>/dev/null | wc -l
       2
My CLAUDE.md was clean, and two skill files matched. A match is only a place to look, not proof. I have not hit this error, so I can’t say those files cause it.
To rule out your setup in one go, the docs say to use --safe-mode. The flag exists in 2.1.330 and a request runs with it:
$ claude --version
2.1.330 (Claude Code)

$ claude --safe-mode -p "Reply with the single word ok" --max-turns 1
ok
Safe mode starts without CLAUDE.md, skills, plugins, hooks and MCP servers. If your prompt works there, one of those holds the trigger. After you change a file, start a new session.
You can still ask why. The docs suggest asking for “a short explanation, the evidence behind a result, or a summary of the actions it took”.
How to fix a cyber block
Step back and take another route, or change model. The errors reference says to press Esc twice or run /rewind, then go back to before the flagged turn.
Claude Code can also switch for you. Per the model docs, a cyber flag on a Fable model or Opus 5.5 re-runs on Opus 4.8. On Sonnet 5.5 it re-runs on Sonnet 5. To choose each time, run /config and set “Switch models when a message is flagged” to “Ask each time”.
If security work is your job, Anthropic points you to its Cyber Verification Program. It needs identity checks, and blocks can still happen after approval. I have not applied.
Workarounds people report, and where each comes from
No single workaround clears every case. This table labels each by its source. “Report” means one user’s account on GitHub, not something I tested.
| Workaround | Source | Notes |
|---|---|---|
| Edit the last message (Esc Esc) | Error text, official docs | The help article says editing “often helps” |
Switch model with /model |
Error text; report #108506 | Opus 5.5 was flagged too. After a switch to Opus 4.6, work went on. In #109730, changing models didn’t help |
New session or /clear |
Official docs; report #110766 | A fresh session’s first message worked. The block returned on --resume |
claude --safe-mode |
Official docs | Finds a trigger in CLAUDE.md, skills or MCP |
| Drop “repeat it verbatim” prompts | Report #109060 | 127 stops in sessions that began that way, 0 in 1,413 messages without it |
| Turn off “inner voice” output | Report #108823 | The reporter switched it off as a test. No result posted yet |
| Rerun a failed subagent on another model | Report #111336 | Done by hand after each block |
Who is affected, and on which models and versions?
Reports come from every platform and the newest models. I searched the anthropics/claude-code repo for “safeguards flagged” on 22 November 2026. It returned 57 issues opened from 8 to 21 November, and 62 in the 14 days before. Fifty-five of the 57 are still open.
| In those 57 issues | Count |
|---|---|
Carry a [cyber] tag |
27 |
Mention reasoning_extraction |
14 |
Carry a [bio] tag |
5 |
| Labelled macOS / Windows / Linux | 29 / 16 / 9 |
| Name Opus 5.5 / Opus 4.8 / Fable 5.2 / Sonnet 5.5 | 22 / 15 / 12 / 9 |
| Versions listed | 2.1.308 to 2.1.330, mostly 2.1.322 (15) and 2.1.325 (14) |
These counts cover issue titles and bodies only. They show who filed a report, not how often the error happens. Updating won’t fix it, because the check runs on Anthropic’s servers.
For reasoning_extraction, the API docs list Fable 5.2, 5.1 and 5, Opus 5.5 and 5, Sonnet 5.5, and Haiku 5.5. One user logged 78 such blocks in a week on two Max accounts (#111336). Eleven of the 57 issues had comments. None was from a maintainer.
What didn’t work / gotchas
- I could not reproduce it. My sessions on 2.1.330 ran normally. Nothing on this page is a first-hand capture of the error.
- The help link changes. Fable reports link to article 15363606. Opus 5.5 and Sonnet 5.5 reports link to 8106465, a general safety page.
- The cyber link redirects. The “real-time-cyber-safeguards” URL now opens the Cyber Verification Program article.
--fallback-modelis not for this. Its help text says it applies “when the main model is busy or unavailable”.- Resuming brings it back. The docs say the transcript on disk “still contains the triggering content”.
- Refunds are unlikely. One user asked support to credit 11 blocked requests and was refused (#109348).
For other Claude Code errors I did reproduce, see Error editing file and organization has disabled subscription access.
FAQ
Is “safeguards flagged this message” a ban or a strike on my account?
The docs I read describe it as one declined request, not an account action. They don’t say whether repeats are counted. If you worry, send /feedback with the Request ID.
Why was a simple “hi” flagged?
The check covers the whole conversation and everything Claude loaded. Reports #108883 and #110766 show greetings blocked. Try the same greeting in claude --safe-mode.
Do I pay for a blocked request?
Sometimes. Anthropic bills a block that arrives before any output for bio, frontier_llm and reasoning_extraction. Blocks for cyber and general_harms before any output are not charged.
Does “safeguards flagged this session” mean something different?
It is the same kind of flag. The docs say Opus 5.5 and Sonnet 5.5 open with “flagged this session”. The fixes are the same.
Can I turn the safeguards off?
No. You can only choose what happens next, in /config or with the switchModelsOnFlag setting. Like DISABLE_TELEMETRY, it changes client behaviour, not the server check.
Sources
- Claude Code errors reference: Safeguards flagged a request for Claude’s reasoning
- Claude Code errors reference: Safety measures flagged a cybersecurity topic
- Claude Code errors reference: Usage Policy refusal
- Claude Code docs: Automatic model fallback
- Claude API docs: Refusals and fallback
- Anthropic help: Why Claude switched models in your conversation with Fable models
- Anthropic help: Our approach to user safety
- Anthropic help: Cyber Verification Program
- GitHub #109211: reasoning_extraction on Fable 5.2
- GitHub #111336: 78 blocked requests across three models